参考链接:笔记
04. Attention MHA GQA
模型架构总览
本节讲解的 Attention 在完整 Transformer Block 中的位置和内部结构:
#mermaid-svg-R5SmpaAwHULlR2n6{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;fill:#333;}@keyframes edge-animation-frame{from{stroke-dashoffset:0;}}@keyframes dash{to{stroke-dashoffset:0;}}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-animation-slow{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 50s linear infinite;stroke-linecap:round;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-animation-fast{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 20s linear infinite;stroke-linecap:round;}#mermaid-svg-R5SmpaAwHULlR2n6 .error-icon{fill:#552222;}#mermaid-svg-R5SmpaAwHULlR2n6 .error-text{fill:#552222;stroke:#552222;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-thickness-normal{stroke-width:1px;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-thickness-thick{stroke-width:3.5px;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-pattern-solid{stroke-dasharray:0;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-thickness-invisible{stroke-width:0;fill:none;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-pattern-dashed{stroke-dasharray:3;}#mermaid-svg-R5SmpaAwHULlR2n6 .edge-pattern-dotted{stroke-dasharray:2;}#mermaid-svg-R5SmpaAwHULlR2n6 .marker{fill:#333333;stroke:#333333;}#mermaid-svg-R5SmpaAwHULlR2n6 .marker.cross{stroke:#333333;}#mermaid-svg-R5SmpaAwHULlR2n6 svg{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;}#mermaid-svg-R5SmpaAwHULlR2n6 p{margin:0;}#mermaid-svg-R5SmpaAwHULlR2n6 .label{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;color:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster-label text{fill:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster-label span{color:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster-label span p{background-color:transparent;}#mermaid-svg-R5SmpaAwHULlR2n6 .label text,#mermaid-svg-R5SmpaAwHULlR2n6 span{fill:#333;color:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 .node rect,#mermaid-svg-R5SmpaAwHULlR2n6 .node circle,#mermaid-svg-R5SmpaAwHULlR2n6 .node ellipse,#mermaid-svg-R5SmpaAwHULlR2n6 .node polygon,#mermaid-svg-R5SmpaAwHULlR2n6 .node path{fill:#ECECFF;stroke:#9370DB;stroke-width:1px;}#mermaid-svg-R5SmpaAwHULlR2n6 .rough-node .label text,#mermaid-svg-R5SmpaAwHULlR2n6 .node .label text,#mermaid-svg-R5SmpaAwHULlR2n6 .image-shape .label,#mermaid-svg-R5SmpaAwHULlR2n6 .icon-shape .label{text-anchor:middle;}#mermaid-svg-R5SmpaAwHULlR2n6 .node .katex path{fill:#000;stroke:#000;stroke-width:1px;}#mermaid-svg-R5SmpaAwHULlR2n6 .rough-node .label,#mermaid-svg-R5SmpaAwHULlR2n6 .node .label,#mermaid-svg-R5SmpaAwHULlR2n6 .image-shape .label,#mermaid-svg-R5SmpaAwHULlR2n6 .icon-shape .label{text-align:center;}#mermaid-svg-R5SmpaAwHULlR2n6 .node.clickable{cursor:pointer;}#mermaid-svg-R5SmpaAwHULlR2n6 .root .anchor path{fill:#333333!important;stroke-width:0;stroke:#333333;}#mermaid-svg-R5SmpaAwHULlR2n6 .arrowheadPath{fill:#333333;}#mermaid-svg-R5SmpaAwHULlR2n6 .edgePath .path{stroke:#333333;stroke-width:2.0px;}#mermaid-svg-R5SmpaAwHULlR2n6 .flowchart-link{stroke:#333333;fill:none;}#mermaid-svg-R5SmpaAwHULlR2n6 .edgeLabel{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-R5SmpaAwHULlR2n6 .edgeLabel p{background-color:rgba(232,232,232, 0.8);}#mermaid-svg-R5SmpaAwHULlR2n6 .edgeLabel rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-R5SmpaAwHULlR2n6 .labelBkg{background-color:rgba(232, 232, 232, 0.5);}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster rect{fill:#ffffde;stroke:#aaaa33;stroke-width:1px;}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster text{fill:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 .cluster span{color:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 div.mermaidTooltip{position:absolute;text-align:center;max-width:200px;padding:2px;font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:12px;background:hsl(80, 100%, 96.2745098039%);border:1px solid #aaaa33;border-radius:2px;pointer-events:none;z-index:100;}#mermaid-svg-R5SmpaAwHULlR2n6 .flowchartTitleText{text-anchor:middle;font-size:18px;fill:#333;}#mermaid-svg-R5SmpaAwHULlR2n6 rect.text{fill:none;stroke-width:0;}#mermaid-svg-R5SmpaAwHULlR2n6 .icon-shape,#mermaid-svg-R5SmpaAwHULlR2n6 .image-shape{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-R5SmpaAwHULlR2n6 .icon-shape p,#mermaid-svg-R5SmpaAwHULlR2n6 .image-shape p{background-color:rgba(232,232,232, 0.8);padding:2px;}#mermaid-svg-R5SmpaAwHULlR2n6 .icon-shape .label rect,#mermaid-svg-R5SmpaAwHULlR2n6 .image-shape .label rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-R5SmpaAwHULlR2n6 .label-icon{display:inline-block;height:1em;overflow:visible;vertical-align:-0.125em;}#mermaid-svg-R5SmpaAwHULlR2n6 .node .label-icon path{fill:currentColor;stroke:revert;stroke-width:revert;}#mermaid-svg-R5SmpaAwHULlR2n6 :root{–mermaid-font-family:\”trebuchet ms\”,verdana,arial,sans-serif;}
输入 x(batch, seq_len, hidden_size)
RMSNormAttention 前
Multi-Head Attention本节重点
残差连接x + Attention(…)
RMSNormMLP 前
SwiGLU MLP
残差连接h + MLP(…)
输出(batch, seq_len, hidden_size)
结构说明: 本节聚焦 A2(Multi-Head Attention)的内部实现,包括 MHA、GQA 和 KV Cache 机制。
Attention 内部架构(同时覆盖 MHA / GQA)
#mermaid-svg-Ij4rbLMaXM44ib6i{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;fill:#333;}@keyframes edge-animation-frame{from{stroke-dashoffset:0;}}@keyframes dash{to{stroke-dashoffset:0;}}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-animation-slow{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 50s linear infinite;stroke-linecap:round;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-animation-fast{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 20s linear infinite;stroke-linecap:round;}#mermaid-svg-Ij4rbLMaXM44ib6i .error-icon{fill:#552222;}#mermaid-svg-Ij4rbLMaXM44ib6i .error-text{fill:#552222;stroke:#552222;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-thickness-normal{stroke-width:1px;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-thickness-thick{stroke-width:3.5px;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-pattern-solid{stroke-dasharray:0;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-thickness-invisible{stroke-width:0;fill:none;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-pattern-dashed{stroke-dasharray:3;}#mermaid-svg-Ij4rbLMaXM44ib6i .edge-pattern-dotted{stroke-dasharray:2;}#mermaid-svg-Ij4rbLMaXM44ib6i .marker{fill:#333333;stroke:#333333;}#mermaid-svg-Ij4rbLMaXM44ib6i .marker.cross{stroke:#333333;}#mermaid-svg-Ij4rbLMaXM44ib6i svg{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;}#mermaid-svg-Ij4rbLMaXM44ib6i p{margin:0;}#mermaid-svg-Ij4rbLMaXM44ib6i .label{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;color:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster-label text{fill:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster-label span{color:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster-label span p{background-color:transparent;}#mermaid-svg-Ij4rbLMaXM44ib6i .label text,#mermaid-svg-Ij4rbLMaXM44ib6i span{fill:#333;color:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i .node rect,#mermaid-svg-Ij4rbLMaXM44ib6i .node circle,#mermaid-svg-Ij4rbLMaXM44ib6i .node ellipse,#mermaid-svg-Ij4rbLMaXM44ib6i .node polygon,#mermaid-svg-Ij4rbLMaXM44ib6i .node path{fill:#ECECFF;stroke:#9370DB;stroke-width:1px;}#mermaid-svg-Ij4rbLMaXM44ib6i .rough-node .label text,#mermaid-svg-Ij4rbLMaXM44ib6i .node .label text,#mermaid-svg-Ij4rbLMaXM44ib6i .image-shape .label,#mermaid-svg-Ij4rbLMaXM44ib6i .icon-shape .label{text-anchor:middle;}#mermaid-svg-Ij4rbLMaXM44ib6i .node .katex path{fill:#000;stroke:#000;stroke-width:1px;}#mermaid-svg-Ij4rbLMaXM44ib6i .rough-node .label,#mermaid-svg-Ij4rbLMaXM44ib6i .node .label,#mermaid-svg-Ij4rbLMaXM44ib6i .image-shape .label,#mermaid-svg-Ij4rbLMaXM44ib6i .icon-shape .label{text-align:center;}#mermaid-svg-Ij4rbLMaXM44ib6i .node.clickable{cursor:pointer;}#mermaid-svg-Ij4rbLMaXM44ib6i .root .anchor path{fill:#333333!important;stroke-width:0;stroke:#333333;}#mermaid-svg-Ij4rbLMaXM44ib6i .arrowheadPath{fill:#333333;}#mermaid-svg-Ij4rbLMaXM44ib6i .edgePath .path{stroke:#333333;stroke-width:2.0px;}#mermaid-svg-Ij4rbLMaXM44ib6i .flowchart-link{stroke:#333333;fill:none;}#mermaid-svg-Ij4rbLMaXM44ib6i .edgeLabel{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-Ij4rbLMaXM44ib6i .edgeLabel p{background-color:rgba(232,232,232, 0.8);}#mermaid-svg-Ij4rbLMaXM44ib6i .edgeLabel rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-Ij4rbLMaXM44ib6i .labelBkg{background-color:rgba(232, 232, 232, 0.5);}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster rect{fill:#ffffde;stroke:#aaaa33;stroke-width:1px;}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster text{fill:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i .cluster span{color:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i div.mermaidTooltip{position:absolute;text-align:center;max-width:200px;padding:2px;font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:12px;background:hsl(80, 100%, 96.2745098039%);border:1px solid #aaaa33;border-radius:2px;pointer-events:none;z-index:100;}#mermaid-svg-Ij4rbLMaXM44ib6i .flowchartTitleText{text-anchor:middle;font-size:18px;fill:#333;}#mermaid-svg-Ij4rbLMaXM44ib6i rect.text{fill:none;stroke-width:0;}#mermaid-svg-Ij4rbLMaXM44ib6i .icon-shape,#mermaid-svg-Ij4rbLMaXM44ib6i .image-shape{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-Ij4rbLMaXM44ib6i .icon-shape p,#mermaid-svg-Ij4rbLMaXM44ib6i .image-shape p{background-color:rgba(232,232,232, 0.8);padding:2px;}#mermaid-svg-Ij4rbLMaXM44ib6i .icon-shape .label rect,#mermaid-svg-Ij4rbLMaXM44ib6i .image-shape .label rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-Ij4rbLMaXM44ib6i .label-icon{display:inline-block;height:1em;overflow:visible;vertical-align:-0.125em;}#mermaid-svg-Ij4rbLMaXM44ib6i .node .label-icon path{fill:currentColor;stroke:revert;stroke-width:revert;}#mermaid-svg-Ij4rbLMaXM44ib6i :root{–mermaid-font-family:\”trebuchet ms\”,verdana,arial,sans-serif;}
输出
Attention 计算
KV Cache
RoPE 旋转
多头切分
Q/K/V 投影
输入 x(batch, seq_len, d)
W_qLinear(d, h*D)
W_kLinear(d, kv_h*D)
W_vLinear(d, kv_h*D)
Q heads(B, H, S, D)
K heads(B, KV_H, S, D)
V heads(B, KV_H, S, D)
Q_rotated
K_rotated
历史 K
历史 V
Q·K^T / sqrt(D)
Causal Mask
Softmax
加权 V
合并多头(B, S, H*D)
W_oLinear(h*D, d)
GQA 架构对比
#mermaid-svg-12EUGRYgPBtaobcB{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;fill:#333;}@keyframes edge-animation-frame{from{stroke-dashoffset:0;}}@keyframes dash{to{stroke-dashoffset:0;}}#mermaid-svg-12EUGRYgPBtaobcB .edge-animation-slow{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 50s linear infinite;stroke-linecap:round;}#mermaid-svg-12EUGRYgPBtaobcB .edge-animation-fast{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 20s linear infinite;stroke-linecap:round;}#mermaid-svg-12EUGRYgPBtaobcB .error-icon{fill:#552222;}#mermaid-svg-12EUGRYgPBtaobcB .error-text{fill:#552222;stroke:#552222;}#mermaid-svg-12EUGRYgPBtaobcB .edge-thickness-normal{stroke-width:1px;}#mermaid-svg-12EUGRYgPBtaobcB .edge-thickness-thick{stroke-width:3.5px;}#mermaid-svg-12EUGRYgPBtaobcB .edge-pattern-solid{stroke-dasharray:0;}#mermaid-svg-12EUGRYgPBtaobcB .edge-thickness-invisible{stroke-width:0;fill:none;}#mermaid-svg-12EUGRYgPBtaobcB .edge-pattern-dashed{stroke-dasharray:3;}#mermaid-svg-12EUGRYgPBtaobcB .edge-pattern-dotted{stroke-dasharray:2;}#mermaid-svg-12EUGRYgPBtaobcB .marker{fill:#333333;stroke:#333333;}#mermaid-svg-12EUGRYgPBtaobcB .marker.cross{stroke:#333333;}#mermaid-svg-12EUGRYgPBtaobcB svg{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;}#mermaid-svg-12EUGRYgPBtaobcB p{margin:0;}#mermaid-svg-12EUGRYgPBtaobcB .label{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;color:#333;}#mermaid-svg-12EUGRYgPBtaobcB .cluster-label text{fill:#333;}#mermaid-svg-12EUGRYgPBtaobcB .cluster-label span{color:#333;}#mermaid-svg-12EUGRYgPBtaobcB .cluster-label span p{background-color:transparent;}#mermaid-svg-12EUGRYgPBtaobcB .label text,#mermaid-svg-12EUGRYgPBtaobcB span{fill:#333;color:#333;}#mermaid-svg-12EUGRYgPBtaobcB .node rect,#mermaid-svg-12EUGRYgPBtaobcB .node circle,#mermaid-svg-12EUGRYgPBtaobcB .node ellipse,#mermaid-svg-12EUGRYgPBtaobcB .node polygon,#mermaid-svg-12EUGRYgPBtaobcB .node path{fill:#ECECFF;stroke:#9370DB;stroke-width:1px;}#mermaid-svg-12EUGRYgPBtaobcB .rough-node .label text,#mermaid-svg-12EUGRYgPBtaobcB .node .label text,#mermaid-svg-12EUGRYgPBtaobcB .image-shape .label,#mermaid-svg-12EUGRYgPBtaobcB .icon-shape .label{text-anchor:middle;}#mermaid-svg-12EUGRYgPBtaobcB .node .katex path{fill:#000;stroke:#000;stroke-width:1px;}#mermaid-svg-12EUGRYgPBtaobcB .rough-node .label,#mermaid-svg-12EUGRYgPBtaobcB .node .label,#mermaid-svg-12EUGRYgPBtaobcB .image-shape .label,#mermaid-svg-12EUGRYgPBtaobcB .icon-shape .label{text-align:center;}#mermaid-svg-12EUGRYgPBtaobcB .node.clickable{cursor:pointer;}#mermaid-svg-12EUGRYgPBtaobcB .root .anchor path{fill:#333333!important;stroke-width:0;stroke:#333333;}#mermaid-svg-12EUGRYgPBtaobcB .arrowheadPath{fill:#333333;}#mermaid-svg-12EUGRYgPBtaobcB .edgePath .path{stroke:#333333;stroke-width:2.0px;}#mermaid-svg-12EUGRYgPBtaobcB .flowchart-link{stroke:#333333;fill:none;}#mermaid-svg-12EUGRYgPBtaobcB .edgeLabel{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-12EUGRYgPBtaobcB .edgeLabel p{background-color:rgba(232,232,232, 0.8);}#mermaid-svg-12EUGRYgPBtaobcB .edgeLabel rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-12EUGRYgPBtaobcB .labelBkg{background-color:rgba(232, 232, 232, 0.5);}#mermaid-svg-12EUGRYgPBtaobcB .cluster rect{fill:#ffffde;stroke:#aaaa33;stroke-width:1px;}#mermaid-svg-12EUGRYgPBtaobcB .cluster text{fill:#333;}#mermaid-svg-12EUGRYgPBtaobcB .cluster span{color:#333;}#mermaid-svg-12EUGRYgPBtaobcB div.mermaidTooltip{position:absolute;text-align:center;max-width:200px;padding:2px;font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:12px;background:hsl(80, 100%, 96.2745098039%);border:1px solid #aaaa33;border-radius:2px;pointer-events:none;z-index:100;}#mermaid-svg-12EUGRYgPBtaobcB .flowchartTitleText{text-anchor:middle;font-size:18px;fill:#333;}#mermaid-svg-12EUGRYgPBtaobcB rect.text{fill:none;stroke-width:0;}#mermaid-svg-12EUGRYgPBtaobcB .icon-shape,#mermaid-svg-12EUGRYgPBtaobcB .image-shape{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-12EUGRYgPBtaobcB .icon-shape p,#mermaid-svg-12EUGRYgPBtaobcB .image-shape p{background-color:rgba(232,232,232, 0.8);padding:2px;}#mermaid-svg-12EUGRYgPBtaobcB .icon-shape .label rect,#mermaid-svg-12EUGRYgPBtaobcB .image-shape .label rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-12EUGRYgPBtaobcB .label-icon{display:inline-block;height:1em;overflow:visible;vertical-align:-0.125em;}#mermaid-svg-12EUGRYgPBtaobcB .node .label-icon path{fill:currentColor;stroke:revert;stroke-width:revert;}#mermaid-svg-12EUGRYgPBtaobcB :root{–mermaid-font-family:\”trebuchet ms\”,verdana,arial,sans-serif;}
KV 头数 H → G
KV 头数 G → 1
MQA
Q 头 1
K 头(全部共享)
V 头(全部共享)
Q 头 2
Q 头 …
Q 头 H
GQA
Q 头 1
K 头 1(共享)
V 头 1(共享)
Q 头 2
Q 头 …
K 头 2(共享)
V 头 2(共享)
Q 头 H
MHA
Q 头 1
K 头 1
V 头 1
Q 头 2
K 头 2
V 头 2
Q 头 …
K 头 …
V 头 …
Q 头 H
K 头 H
V 头 H
本节讲解的模型架构模块
| Q 投影 | #2.1, #3.1 | [B, S, d] → [B, S, H*D] | 生成 Query 向量 |
| K/V 投影 | #2.1, #3.1 | [B, S, d] → [B, S, G*D] | GQA 中只生成 G=num_kv_heads 组 K/V |
| 多头切分 | #3.1 | [B, S, H*D] → [B, H, S, D] | 分离注意力头 |
| KV Cache 拼接 | #3.2 | [B, G, past_len, D] + [B, G, S_q, D] → [B, G, S_kv, D] | 复用历史 K/V,避免为历史 token 重复生成 K/V |
| repeat_kv | #3.2 | [B, KV_H, S, D] → [B, H, S, D] | GQA 扩充 KV 头 |
| 注意力分数 | #3.3 | Q·K^T / sqrt(D) → [B, H, S_q, S_kv] | 每个 Query 位置与可见 Key 位置计算相关性 |
| Softmax | #3.3 | [B, H, S_q, S_kv] | 沿最后一个 S_kv 维归一化 |
| 加权 V | #3.3 | probs·V → [B, H, S_q, D] | 按注意力权重聚合 Value |
| 输出投影 | #3.4 | [B, S, H*D] → [B, S, d] | 合并多头 |
数据流详解(含具体数值)
#mermaid-svg-xrArwJiu7QIREQKm{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;fill:#333;}@keyframes edge-animation-frame{from{stroke-dashoffset:0;}}@keyframes dash{to{stroke-dashoffset:0;}}#mermaid-svg-xrArwJiu7QIREQKm .edge-animation-slow{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 50s linear infinite;stroke-linecap:round;}#mermaid-svg-xrArwJiu7QIREQKm .edge-animation-fast{stroke-dasharray:9,5!important;stroke-dashoffset:900;animation:dash 20s linear infinite;stroke-linecap:round;}#mermaid-svg-xrArwJiu7QIREQKm .error-icon{fill:#552222;}#mermaid-svg-xrArwJiu7QIREQKm .error-text{fill:#552222;stroke:#552222;}#mermaid-svg-xrArwJiu7QIREQKm .edge-thickness-normal{stroke-width:1px;}#mermaid-svg-xrArwJiu7QIREQKm .edge-thickness-thick{stroke-width:3.5px;}#mermaid-svg-xrArwJiu7QIREQKm .edge-pattern-solid{stroke-dasharray:0;}#mermaid-svg-xrArwJiu7QIREQKm .edge-thickness-invisible{stroke-width:0;fill:none;}#mermaid-svg-xrArwJiu7QIREQKm .edge-pattern-dashed{stroke-dasharray:3;}#mermaid-svg-xrArwJiu7QIREQKm .edge-pattern-dotted{stroke-dasharray:2;}#mermaid-svg-xrArwJiu7QIREQKm .marker{fill:#333333;stroke:#333333;}#mermaid-svg-xrArwJiu7QIREQKm .marker.cross{stroke:#333333;}#mermaid-svg-xrArwJiu7QIREQKm svg{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:16px;}#mermaid-svg-xrArwJiu7QIREQKm p{margin:0;}#mermaid-svg-xrArwJiu7QIREQKm .label{font-family:\”trebuchet ms\”,verdana,arial,sans-serif;color:#333;}#mermaid-svg-xrArwJiu7QIREQKm .cluster-label text{fill:#333;}#mermaid-svg-xrArwJiu7QIREQKm .cluster-label span{color:#333;}#mermaid-svg-xrArwJiu7QIREQKm .cluster-label span p{background-color:transparent;}#mermaid-svg-xrArwJiu7QIREQKm .label text,#mermaid-svg-xrArwJiu7QIREQKm span{fill:#333;color:#333;}#mermaid-svg-xrArwJiu7QIREQKm .node rect,#mermaid-svg-xrArwJiu7QIREQKm .node circle,#mermaid-svg-xrArwJiu7QIREQKm .node ellipse,#mermaid-svg-xrArwJiu7QIREQKm .node polygon,#mermaid-svg-xrArwJiu7QIREQKm .node path{fill:#ECECFF;stroke:#9370DB;stroke-width:1px;}#mermaid-svg-xrArwJiu7QIREQKm .rough-node .label text,#mermaid-svg-xrArwJiu7QIREQKm .node .label text,#mermaid-svg-xrArwJiu7QIREQKm .image-shape .label,#mermaid-svg-xrArwJiu7QIREQKm .icon-shape .label{text-anchor:middle;}#mermaid-svg-xrArwJiu7QIREQKm .node .katex path{fill:#000;stroke:#000;stroke-width:1px;}#mermaid-svg-xrArwJiu7QIREQKm .rough-node .label,#mermaid-svg-xrArwJiu7QIREQKm .node .label,#mermaid-svg-xrArwJiu7QIREQKm .image-shape .label,#mermaid-svg-xrArwJiu7QIREQKm .icon-shape .label{text-align:center;}#mermaid-svg-xrArwJiu7QIREQKm .node.clickable{cursor:pointer;}#mermaid-svg-xrArwJiu7QIREQKm .root .anchor path{fill:#333333!important;stroke-width:0;stroke:#333333;}#mermaid-svg-xrArwJiu7QIREQKm .arrowheadPath{fill:#333333;}#mermaid-svg-xrArwJiu7QIREQKm .edgePath .path{stroke:#333333;stroke-width:2.0px;}#mermaid-svg-xrArwJiu7QIREQKm .flowchart-link{stroke:#333333;fill:none;}#mermaid-svg-xrArwJiu7QIREQKm .edgeLabel{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-xrArwJiu7QIREQKm .edgeLabel p{background-color:rgba(232,232,232, 0.8);}#mermaid-svg-xrArwJiu7QIREQKm .edgeLabel rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-xrArwJiu7QIREQKm .labelBkg{background-color:rgba(232, 232, 232, 0.5);}#mermaid-svg-xrArwJiu7QIREQKm .cluster rect{fill:#ffffde;stroke:#aaaa33;stroke-width:1px;}#mermaid-svg-xrArwJiu7QIREQKm .cluster text{fill:#333;}#mermaid-svg-xrArwJiu7QIREQKm .cluster span{color:#333;}#mermaid-svg-xrArwJiu7QIREQKm div.mermaidTooltip{position:absolute;text-align:center;max-width:200px;padding:2px;font-family:\”trebuchet ms\”,verdana,arial,sans-serif;font-size:12px;background:hsl(80, 100%, 96.2745098039%);border:1px solid #aaaa33;border-radius:2px;pointer-events:none;z-index:100;}#mermaid-svg-xrArwJiu7QIREQKm .flowchartTitleText{text-anchor:middle;font-size:18px;fill:#333;}#mermaid-svg-xrArwJiu7QIREQKm rect.text{fill:none;stroke-width:0;}#mermaid-svg-xrArwJiu7QIREQKm .icon-shape,#mermaid-svg-xrArwJiu7QIREQKm .image-shape{background-color:rgba(232,232,232, 0.8);text-align:center;}#mermaid-svg-xrArwJiu7QIREQKm .icon-shape p,#mermaid-svg-xrArwJiu7QIREQKm .image-shape p{background-color:rgba(232,232,232, 0.8);padding:2px;}#mermaid-svg-xrArwJiu7QIREQKm .icon-shape .label rect,#mermaid-svg-xrArwJiu7QIREQKm .image-shape .label rect{opacity:0.5;background-color:rgba(232,232,232, 0.8);fill:rgba(232,232,232, 0.8);}#mermaid-svg-xrArwJiu7QIREQKm .label-icon{display:inline-block;height:1em;overflow:visible;vertical-align:-0.125em;}#mermaid-svg-xrArwJiu7QIREQKm .node .label-icon path{fill:currentColor;stroke:revert;stroke-width:revert;}#mermaid-svg-xrArwJiu7QIREQKm :root{–mermaid-font-family:\”trebuchet ms\”,verdana,arial,sans-serif;}
Step 5: 输出投影#3.4
W_o: (4096, 4096)
Step 4: Attention 计算#3.3
scores: (2, 32, 16, 21)
softmax
output: (2, 32, 16, 128)
Step 3: repeat_kv#3.2
K: (2, 32, 21, 128)
V: (2, 32, 21, 128)
Step 2: 多头切分 + KV Cache示例 past_len=5
Q: (2, 32, 16, 128)
K: (2, 8, 21, 128)
V: (2, 8, 21, 128)
Step 1: Q/K/V 投影#3.1
q_proj.weight: (4096, 4096)PyTorch [out,in]
k_proj.weight: (1024, 4096)PyTorch [out,in]
v_proj.weight: (1024, 4096)PyTorch [out,in]
输入 x(2, 16, 4096)
输出(2, 16, 4096)
0. 学习本章前先认识这些名词
Attention 的实现涉及多头机制、KV Cache 和分组策略,需要先建立对这三个概念的基本理解。
0.1 注意力基础
| 注意力 | Attention | 让模型聚焦相关部分 | 核心机制 |
| Query | Q | 当前查询位置用于“匹配”的向量 | 寻找相关 Key |
| Key | K | 每个可见位置用于“被匹配”的向量 | 与 Query 计算相关性 |
| Value | V | 每个可见位置提供给聚合的内容向量 | 根据注意力权重被加权求和 |
| 缩放点积 | Scaled Dot-Product | Q·K^T / sqrt(d) | 计算相关性分数 |
必须先懂: 注意力机制的基本直觉(Q 提问、K 匹配、V 回答)。
0.2 多头机制
| 注意力头 | Attention Head | 独立学习的注意力子空间 | 并行计算多组 Q/K/V |
| 多头注意力 | Multi-Head Attention | 多个注意力头并行 | MHA 标准实现 |
| 分组查询 | Grouped Query | 多个 Q 头共享一个 K/V 头 | GQA 的核心思想 |
| 多查询 | Multi-Query | 所有 Q 头共享一个 K/V 头 | MQA 的极端情况 |
必须先懂: 为什么需要多个注意力头(不同头学习不同类型的依赖关系)。
0.3 推理优化
| KV Cache | KV Cache | 缓存历史 K/V 避免重复计算 | 自回归生成加速 |
| 自回归 | Autoregressive | 逐个生成 token | KV Cache 的使用场景 |
| 因果掩码 | Causal Mask | 当前 token 只能看到历史 | 防止信息泄露 |
必须先懂: 自回归生成的推理流程(生成第
N
N
N 个 token 需要前
N
−
1
N-1
N−1 个 token 的信息)。
0.4 数学符号
|
H H H |
Query 头数 | num_heads |
|
G G G |
KV 头数(分组数) | num_kv_heads |
|
D D D |
每个头的维度 | head_dim = hidden_dim / H |
|
S S S |
序列长度 | seq_len |
|
g = H / G g = H/G g=H/G |
每个 KV 头对应的 Q 头数 | GQA 的核心参数 |
0.5 维度关系
| MHA |
H H H |
2 × H × D × b 2 \\times H \\times D \\times b 2×H×D×b bytes |
原始 Transformer |
| GQA |
G G G( 1 < G < H 1 < G < H 1<G<H) |
2 × G × D × b 2 \\times G \\times D \\times b 2×G×D×b bytes |
LLaMA-2 70B、LLaMA 3 等 |
| MQA |
1 1 1 |
2 × 1 × D × b 2 \\times 1 \\times D \\times b 2×1×D×b bytes |
部分 MQA 模型 |
其中 b 是每个缓存元素的字节数,例如 FP16/BF16 通常为 2 bytes,FP32 为 4 bytes。KV Cache 大小必须和实际 dtype 一起计算。
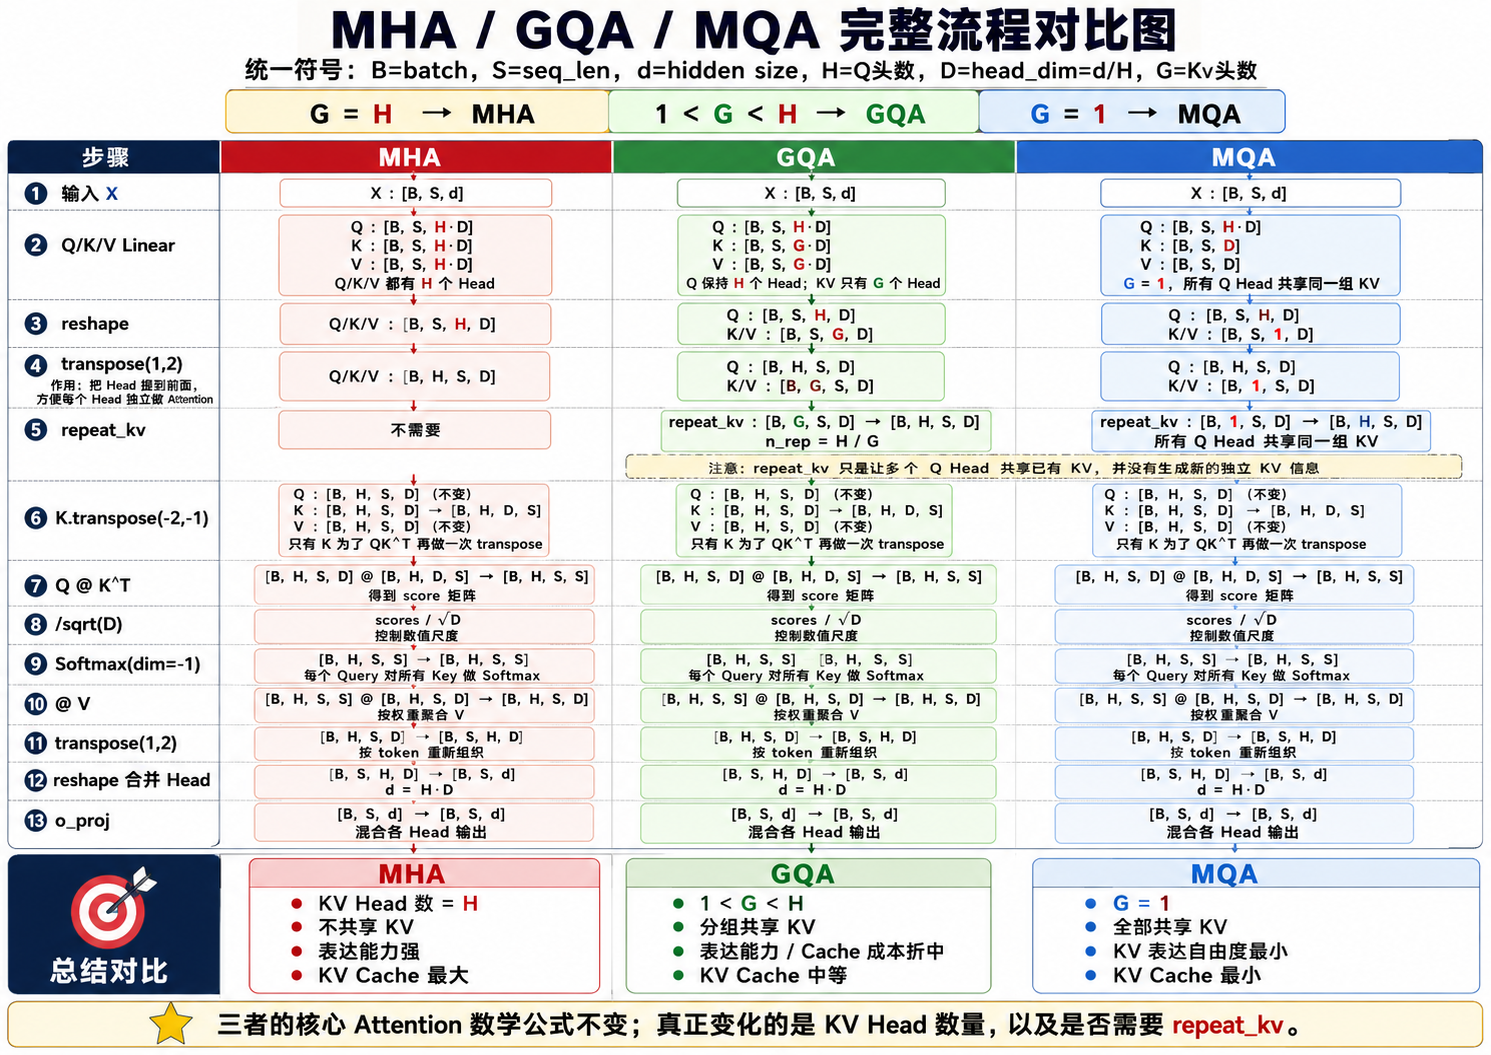
1. 从 MHA 到 GQA:架构演进
1.1 MHA:标准多头注意力
结构:
Q: [batch, seq, H, D]
K: [batch, seq, H, D] ← 每个 Q 头有独立的 K/V
V: [batch, seq, H, D]
Attention = softmax(Q·K^T / sqrt(D)) · V
优点:
- 每个 Q 头拥有独立 K/V 头,参数与 KV 表示更充分;但不能简单断言所有任务上“一定最强”
- 标准实现,兼容性好
缺点:
- KV Cache 显存占用大(与 Q 头数成正比)
- 解码阶段常受到 KV Cache 读取带宽和容量的显著影响,尤其在长上下文或较大 batch 下
1.2 MQA:极致压缩
结构:
Q: [batch, seq, H, D]
K: [batch, seq, 1, D] ← 所有 Q 头共享 1 个 K/V
V: [batch, seq, 1, D]
K = repeat(K, H) → [batch, seq, H, D]
V = repeat(V, H) → [batch, seq, H, D]
优点:
- KV Cache 仅为 MHA 的 1/H
- 推理速度大幅提升
缺点:
- K/V 头共享程度最高,表示容量更受约束
- 相比 MHA/GQA 可能带来质量损失,但损失大小依模型和训练方式而定
1.3 GQA:折中方案
结构:
Q: [batch, seq, H, D]
K: [batch, seq, G, D] ← 共 G 个 KV 头;每个 KV 头对应 H/G 个 Q 头
V: [batch, seq, G, D]
K = repeat(K, H/G) → [batch, seq, H, D]
V = repeat(V, H/G) → [batch, seq, H, D]
优点:
- KV Cache 为 MHA 的 G/H(如 8/64 = 1/8)
- 保留更多 KV 表达能力,效果损失小
LLaMA-2/3 配置示例:
| LLaMA-2 7B | 4096 | 32 | 32 | 1x(MHA) |
| LLaMA-2 70B | 8192 | 64 | 8 | 8x |
| LLaMA-3 8B | 4096 | 32 | 8 | 4x |
| LLaMA-3 70B | 8192 | 64 | 8 | 8x |
2. 核心公式与张量维度
2.1 Scaled Dot-Product Attention
Attention
(
Q
,
K
,
V
)
=
Softmax
(
Q
K
T
d
k
)
V
\\text{Attention}(Q, K, V) = \\text{Softmax}\\left(\\frac{QK^T}{\\sqrt{d_k}}\\right)V
Attention(Q,K,V)=Softmax(dk
QKT)V
为什么除以
d
k
\\sqrt{d_k}
dk
?
防止点积结果过大,导致 Softmax 梯度消失:
- 假设 Q, K 的元素均值为 0,方差为 1
-
Q
⋅
K
Q \\cdot K
Q⋅K 的方差 =d
k
d_k
dk - 除以
d
k
\\sqrt{d_k}
dk 使方差回到 1
2.2 张量维度追踪
输入: x: [batch, seq_len, hidden_dim]
步骤 1:线性投影
数学上把每个 token 表示看成行向量:
Q = x @ W_q → [batch, seq_len, num_heads * head_dim]
K = x @ W_k → [batch, seq_len, num_kv_heads * head_dim]
V = x @ W_v → [batch, seq_len, num_kv_heads * head_dim]
其中数学权重可写为 W_q:[d, H*D]、W_k/W_v:[d, G*D]。
PyTorch nn.Linear(in_features, out_features) 内部的 weight 按 [out_features, in_features] 存储,所以代码等价于:
Q = x @ q_proj.weight.T
K = x @ k_proj.weight.T
V = x @ v_proj.weight.T
数学结构没有改变,只是 PyTorch 的权重存储约定不同。
步骤 2:多头切分
xq = xq.reshape(batch, seq_len, num_heads, head_dim).transpose(1, 2)
→ [batch, num_heads, seq_len, head_dim]
xk = xk.reshape(batch, seq_len, num_kv_heads, head_dim).transpose(1, 2)
→ [batch, num_kv_heads, seq_len, head_dim]
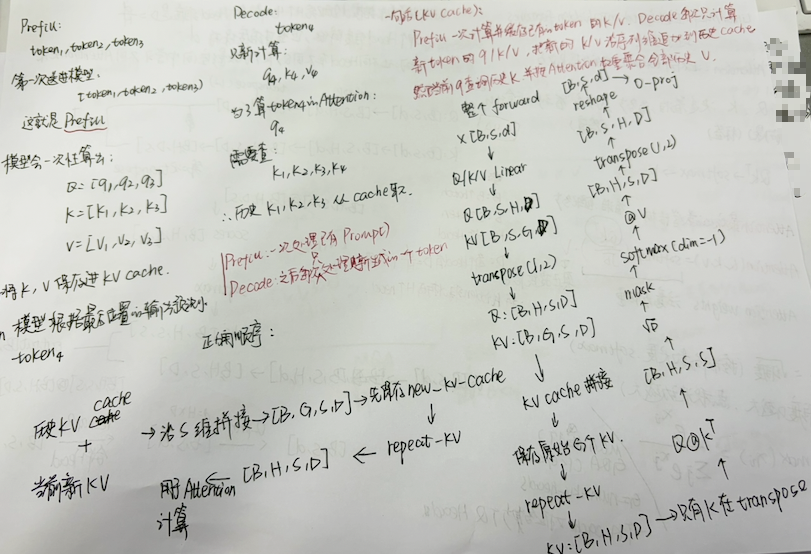
步骤 3:KV Cache 拼接(推理时)
if kv_cache:
xk = torch.cat([k_cache, xk], dim=2)
xv = torch.cat([v_cache, xv], dim=2)
步骤 4:repeat_kv 扩充
xk = repeat_kv(xk, num_heads // num_kv_heads)
→ [batch, num_heads, seq_len, head_dim]
步骤 5:注意力计算
scores = xq @ xk.transpose(-2, -1) / sqrt(head_dim)
→ [batch, num_heads, query_len, kv_len]
probs = softmax(scores, dim=-1)
output = probs @ xv
→ [batch, num_heads, seq_len, head_dim]
步骤 6:输出投影
output = output.transpose(1, 2).reshape(batch, seq_len, -1)
→ [batch, seq_len, num_heads * head_dim]
output = output @ W_o
→ [batch, seq_len, hidden_dim]
数学上 W_o:[H*D, d];PyTorch o_proj.weight:[d, H*D],实际仍是 output @ o_proj.weight.T。
理论结构 vs 本章教学代码: 真实 LLaMA/Qwen 类模型通常会在 Q/K 切头之后对 Q/K 应用 RoPE,并把旋转后的 K写入 KV Cache。本章下面的最小代码为了单独练习 MHA/GQA/KV Cache,没有实现 RoPE;不要把这个省略理解为真实 LLM 没有位置编码。
3. 动手实战
3.1 任务要求
请补全 GroupedQueryAttention.forward 函数中的 TODO 部分。
import torch
import torch.nn as nn
import math
import torch.nn.functional as F
def repeat_kv(hidden_states: torch.Tensor, n_rep: int) –> torch.Tensor:
"""将 KV 头复制 n_rep 次以匹配 Query 头数"""
batch, num_kv_heads, slen, head_dim = hidden_states.shape
if n_rep == 1:
return hidden_states
hidden_states = hidden_states.unsqueeze(2).expand(–1, –1, n_rep, –1, –1)
return hidden_states.reshape(batch, num_kv_heads * n_rep, slen, head_dim)
class GroupedQueryAttention(nn.Module):
def __init__(self, hidden_dim: int, num_heads: int, num_kv_heads: int = None):
super().__init__()
self.hidden_dim = hidden_dim
self.num_heads = num_heads
self.num_kv_heads = num_kv_heads if num_kv_heads is not None else num_heads
assert num_heads % self.num_kv_heads == 0
assert hidden_dim % num_heads == 0, "hidden_dim 必须能被 num_heads 整除"
self.num_queries_per_kv = self.num_heads // self.num_kv_heads
self.head_dim = hidden_dim // num_heads
self.q_proj = nn.Linear(hidden_dim, num_heads * self.head_dim, bias=False)
self.k_proj = nn.Linear(hidden_dim, self.num_kv_heads * self.head_dim, bias=False)
self.v_proj = nn.Linear(hidden_dim, self.num_kv_heads * self.head_dim, bias=False)
self.o_proj = nn.Linear(num_heads * self.head_dim, hidden_dim, bias=False)
def forward(
self,
x: torch.Tensor,
attention_mask: torch.Tensor = None,
kv_cache: tuple[torch.Tensor, torch.Tensor] = None,
):
batch_size, seq_len, _ = x.shape
# 线性投影
xq, xk, xv = self.q_proj(x), self.k_proj(x), self.v_proj(x)
# ==========================================
# TODO 1: Reshape xq, xk, xv 以适配多头
# 提示:
# 1. reshape(batch, seq_len, num_heads, head_dim)
# 2. transpose(1, 2) 将 heads 维移到第 2 维
# 3. xk, xv 使用 num_kv_heads
# ==========================================
# xq = ???
# xk = ???
# xv = ???
# ==========================================
# TODO 2: 处理 KV Cache
# 提示:
# 1. 如果有 cache,在 dim=2 (seq_len 维) 拼接历史 K/V
# 2. 先拼接,再 repeat_kv
# ==========================================
if kv_cache is not None:
k_cache, v_cache = kv_cache
# xk = ???
# xv = ???
new_kv_cache = (xk, xv)
# 扩充 KV 头数
xk = repeat_kv(xk, self.num_queries_per_kv)
xv = repeat_kv(xv, self.num_queries_per_kv)
# ==========================================
# TODO 3: 计算注意力分数
# 提示:
# 1. scores = xq @ xk.transpose(-2, -1) / sqrt(head_dim)
# 2. 添加 attention_mask(广播)
# 3. probs = F.softmax(scores, dim=-1)
# 4. output = probs @ xv
# ==========================================
# scores = ???
if attention_mask is not None:
scores = scores + attention_mask
# probs = ???
# output = ???
# ==========================================
# TODO 4: 恢复形状
# 提示:
# 1. transpose(1, 2) 恢复 [B, S, H, D]
# 2. reshape(batch, seq_len, -1) 合并多头
# ==========================================
# output = ???
return self.o_proj(output), new_kv_cache
3.2 测试代码
def test_mha_mqa_gqa():
try:
batch_size, seq_len, hidden_dim, num_heads = 2, 16, 128, 4
# 测试 1:MHA
print("Testing MHA (Multi-Head Attention)…")
mha = GroupedQueryAttention(hidden_dim, num_heads, num_kv_heads=num_heads)
x = torch.randn(batch_size, seq_len, hidden_dim)
out, _ = mha(x)
assert out.shape == (batch_size, seq_len, hidden_dim)
# 测试 2:GQA
print("Testing GQA (Grouped-Query Attention)…")
gqa = GroupedQueryAttention(hidden_dim, num_heads, num_kv_heads=2)
out, _ = gqa(x)
assert out.shape == (batch_size, seq_len, hidden_dim)
# 测试 3:KV Cache
print("Testing KV Cache…")
prefill_len = 5
x_prefill = torch.randn(batch_size, prefill_len, hidden_dim)
_, kv_cache = mha(x_prefill)
x_decode = torch.randn(batch_size, 1, hidden_dim)
out_decode, new_kv_cache = mha(x_decode, kv_cache=kv_cache)
assert new_kv_cache[0].shape[2] == prefill_len + 1
print("\\n✅ All Tests Passed! Attention 算子实现通过测试。")
except NotImplementedError:
print("请先完成 TODO 部分的代码!")
raise
test_mha_mqa_gqa()
4. 参考代码与解析
4.1 完整实现
def repeat_kv(hidden_states: torch.Tensor, n_rep: int) –> torch.Tensor:
"""将 KV 头复制 n_rep 次以匹配 Query 头数"""
batch, num_kv_heads, slen, head_dim = hidden_states.shape
if n_rep == 1:
return hidden_states
hidden_states = hidden_states.unsqueeze(2).expand(–1, –1, n_rep, –1, –1)
return hidden_states.reshape(batch, num_kv_heads * n_rep, slen, head_dim)
class GroupedQueryAttention(nn.Module):
def __init__(self, hidden_dim: int, num_heads: int, num_kv_heads: int = None):
super().__init__()
self.hidden_dim = hidden_dim
self.num_heads = num_heads
self.num_kv_heads = num_kv_heads if num_kv_heads is not None else num_heads
assert num_heads % self.num_kv_heads == 0
assert hidden_dim % num_heads == 0, "hidden_dim 必须能被 num_heads 整除"
self.num_queries_per_kv = self.num_heads // self.num_kv_heads
self.head_dim = hidden_dim // num_heads
self.q_proj = nn.Linear(hidden_dim, num_heads * self.head_dim, bias=False)
self.k_proj = nn.Linear(hidden_dim, self.num_kv_heads * self.head_dim, bias=False)
self.v_proj = nn.Linear(hidden_dim, self.num_kv_heads * self.head_dim, bias=False)
self.o_proj = nn.Linear(num_heads * self.head_dim, hidden_dim, bias=False)
def forward(
self,
x: torch.Tensor,
attention_mask: torch.Tensor = None,
kv_cache: tuple[torch.Tensor, torch.Tensor] = None,
):
batch_size, seq_len, _ = x.shape
xq, xk, xv = self.q_proj(x), self.k_proj(x), self.v_proj(x)
# TODO 1: Reshape 为多头形式
xq = xq.reshape(batch_size, seq_len, self.num_heads, self.head_dim).transpose(1, 2)
xk = xk.reshape(batch_size, seq_len, self.num_kv_heads, self.head_dim).transpose(1, 2)
xv = xv.reshape(batch_size, seq_len, self.num_kv_heads, self.head_dim).transpose(1, 2)
# TODO 2: 处理 KV Cache
if kv_cache is not None:
k_cache, v_cache = kv_cache
xk = torch.cat([k_cache, xk], dim=2)
xv = torch.cat([v_cache, xv], dim=2)
new_kv_cache = (xk, xv)
# 扩充 KV 头数
xk = repeat_kv(xk, self.num_queries_per_kv)
xv = repeat_kv(xv, self.num_queries_per_kv)
# TODO 3: Scaled Dot-Product Attention
scores = torch.matmul(xq, xk.transpose(2, 3)) / math.sqrt(self.head_dim)
if attention_mask is not None:
scores = scores + attention_mask
probs = F.softmax(scores, dim=–1)
output = torch.matmul(probs, xv)
# TODO 4: 恢复形状
output = output.transpose(1, 2).reshape(batch_size, seq_len, –1)
return self.o_proj(output), new_kv_cache
5.实现理解
| MHA | (H) | (G=H) | (H/G=1) | [B,H,S,D] | [B,H,S,D] | 每个 Q Head 有自己的 K/V Head |
| GQA | (H) | (1<G<H) | (H/G) | [B,H,S,D] | [B,G,S,D] | 一组 Q Heads 共享一个 K/V Head |
| MQA | (H) | (G=1) | (H) | [B,H,S,D] | [B,1,S,D] | 所有 Q Heads 共享同一个 K/V Head |